Getting started with Keboola
Build one working, scheduled pipeline: load six tables, join them with SQL, ask the result a question, turn it into an app, and have it rebuild itself every morning.
Your data lives in more places than one: files, a spreadsheet someone keeps, an API, a database. Keboola is where you bring it together, shape it with SQL, ask it questions in plain language, turn the answer into an app, and have the pipeline rerun by itself every morning. This guide does each of those once, on a small sample, so you can do them on your own data.
Where you are: you have heard of Keboola and have nothing set up. When you finish: a scheduled pipeline and a data app, in a project you created or joined.
The sample is six café branches: five files with a summer of sales, the rosters that served it and the weather, plus next week’s forecast from a public API that needs no account. No file answers anything alone, and the moves are the same on your own tables. Every step works toward one question: Which day next week will leave a café short-handed? By the fifth page a grid answers it, and the answer changes every morning with the forecast.
Everything here can be done in the browser with nothing installed; the command-line way on each page needs kbagent. A free project is enough to begin.
What you get
Section titled “What you get”| Step | What you’ll be able to do | Keboola calls it | Minutes |
|---|---|---|---|
| Get a project | create or join a project, the place everything below lives in | a project | 5 |
| Get your data in | load five files and a live API into six tables, from configurations you can re-run | a data source connector | 15 |
| Transform data | join five of them with SQL into one table: a café, a day, the demand to expect, the crew rostered, a flag | a transformation | 15 |
| Ask a question and get an answer | ask that table a question in plain words and get an answer that says why | Kai reading your data | 5 |
| Put it in front of someone | describe an app in a paragraph and get a grid: six cafés by seven days, red where it will hurt | a data app | 15 |
| Make it run every morning | schedule all of it to re-run on the new forecast, and hear about it if it breaks | a flow | 15 |
| Check it worked | read what Storage and Jobs should show, and recognise the failures that happen | — | 5 |
Read the steps in order, or land on any one of them: each says where you should be, what it needs, and how to tell it worked. The Next control at the foot of every page follows this order.
How every page works
Section titled “How every page works”Every page with a task on it offers that task three ways, and your choice follows you from page to page:
- Prompt: paste it into Kai, the assistant in the project’s top bar, and watch it build. Kai asks before it changes anything: one approval per object it creates, while questions that only read do not ask. An organization admin switches the feature on; see Get started with Kai.
- UI: the same task click by click, for when you want to see where each setting lives.
- CLI / API: the same task from a terminal with kbagent, and the raw request beside it where there is no command for it.
Pick a tab once and every page after it opens on the same one:
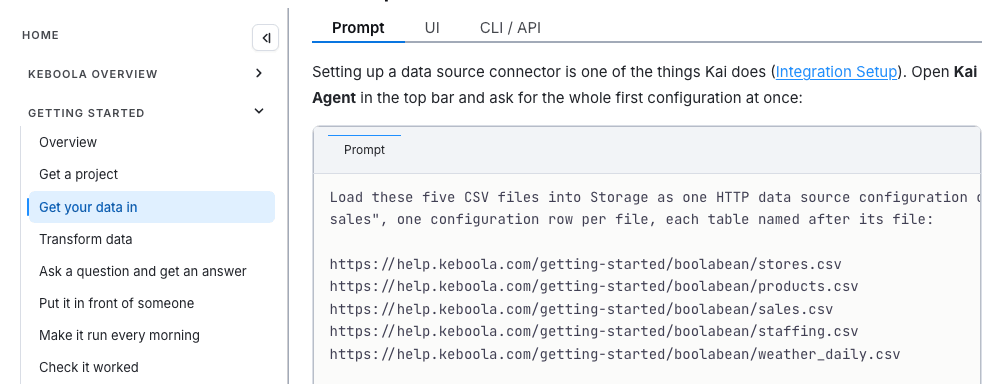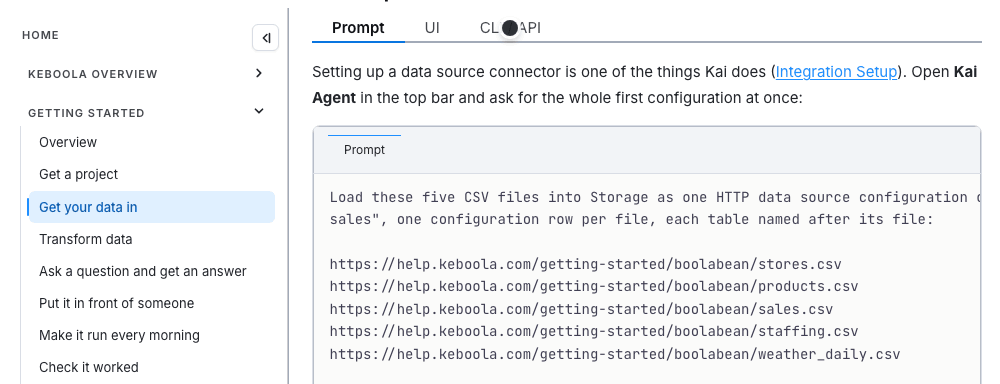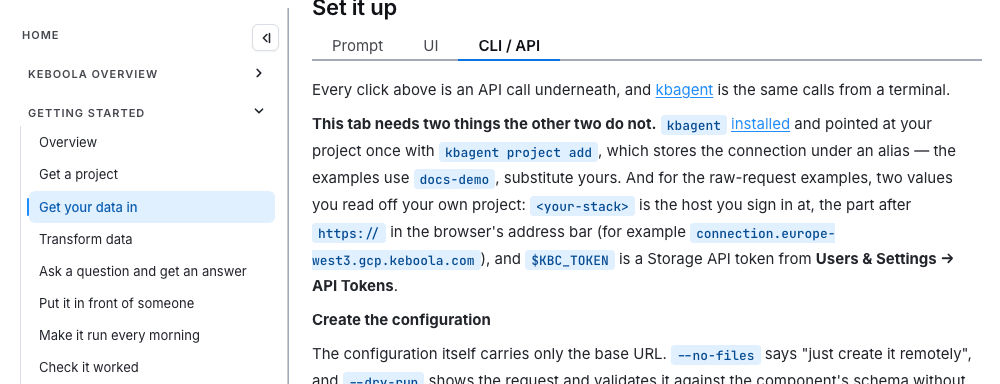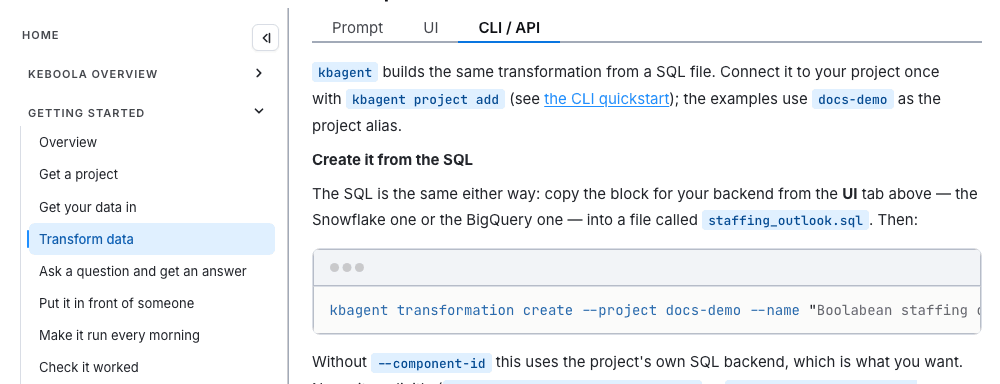
Where one of the three cannot do the job, the page says so rather than showing an empty tab. A signup form, a Google consent screen and a branch merge are all decisions a browser has to make.
Nothing here is one-way: if a step builds something other than what the page describes, say so in the same Kai chat, or edit the configuration by hand.
Where to start instead
Section titled “Where to start instead”This guide is the browser path. Three others start from the same place:
| Quickstart | Description |
|---|---|
| This guide | Build a scheduled pipeline and a data app in the browser, prompt first. |
| kbagent CLI | The same operations from a terminal, scriptable and agent-friendly. |
| MCP server | Connect your own AI assistant or IDE to a Keboola project. |
| Build an app with Kai | Go straight to a data app on data you already have. |
Going further
Section titled “Going further”Optional side trips, once the main path makes sense. None of them are needed to finish the guide:
- Send a table to Google Sheets delivers the result to where people read it. It needs a Google account you can authorize.
- Load from Google Sheets and from a database load from a source that needs credentials rather than from a public URL.
- Use a workspace is where you develop and test SQL against a copy of your data before committing it to a transformation.
- Ad-hoc data analysis explores data in a Python or R notebook instead of building a pipeline.
- Development branches change a running project safely: make the change, review the diff, then merge.
If you are planning a rollout, not learning the tool
Section titled “If you are planning a rollout, not learning the tool”This guide is for one person building one pipeline. For introducing Keboola to a team, with project architecture, a data model, naming conventions and governance, start with Platform Onboarding instead.